FIRE/J, eighteen years later: the JIT took its cut
September 7, 2026 · Programming
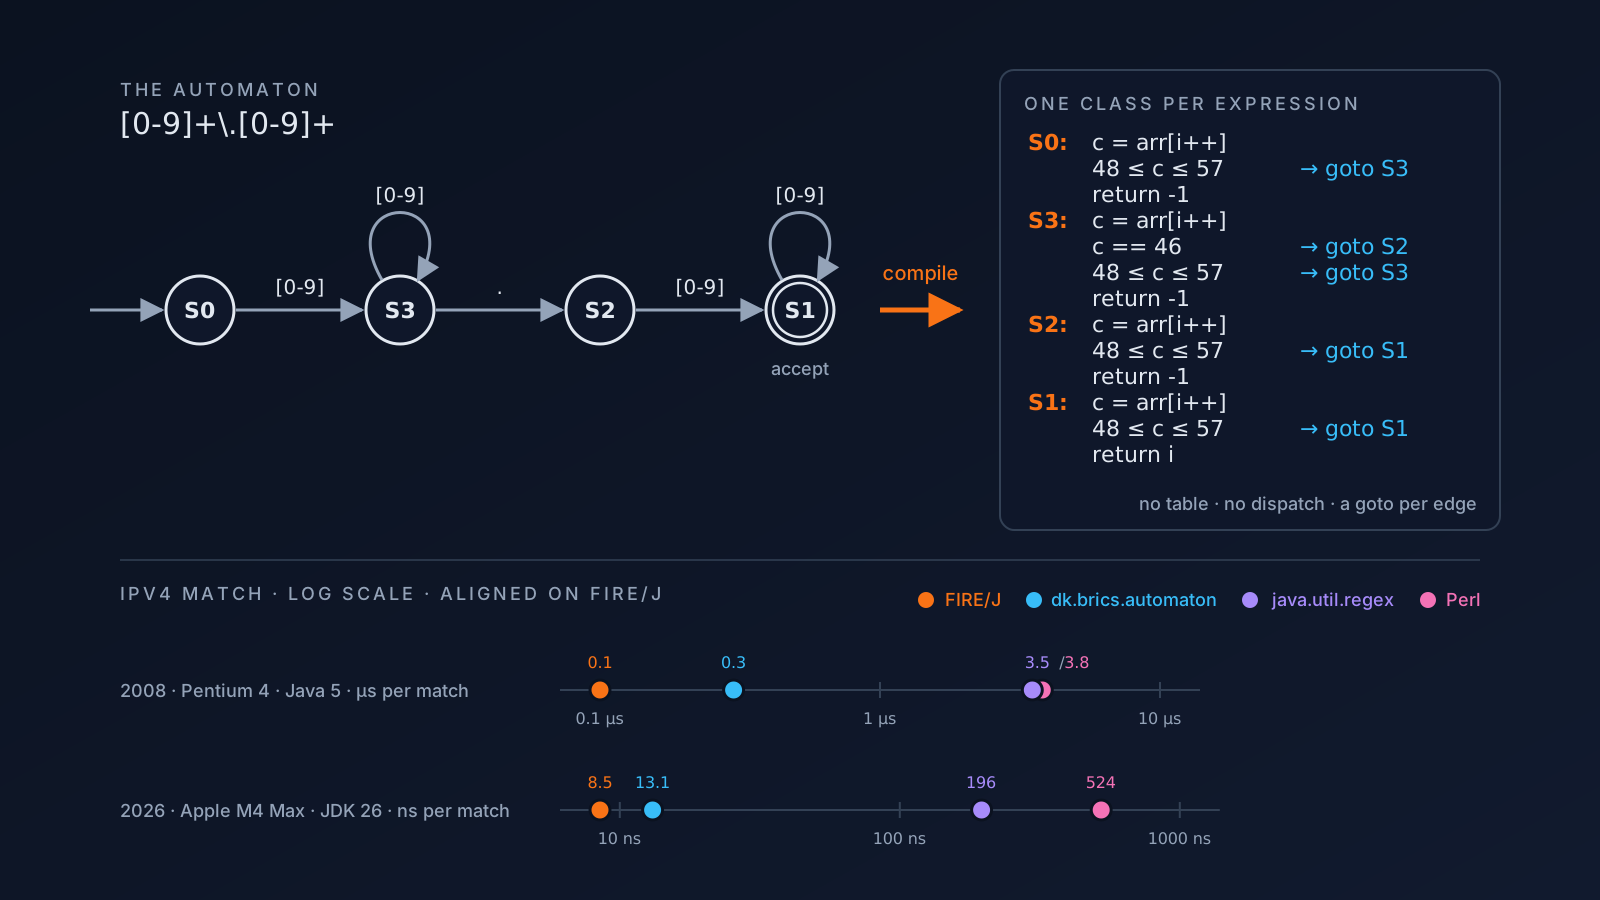
[0-9]+\.[0-9]+ compiled into a class, one block per state and a goto per edge. Below it, the IPv4 match times of 2008 and 2026 on a log scale, aligned on FIRE/J: the engines moved a thousandfold, their spacing barely did.In 2007 Diomidis Spinellis and I wrote a paper about a regular expression engine that cheats. Instead of interpreting an automaton, FIRE/J turns every expression into a JVM class of its own: the DFA becomes straight-line bytecode, one block per state, a goto per transition, and the JVM's just-in-time compiler turns that into native code. The paper came out in Software: Practice and Experience the year after, with a benchmark that put the generated code well ahead of everything else on the JVM and of the C libraries too. The measurements were made on a 2.8 GHz Pentium 4 with Java 5.
What FIRE/J is, in one example
For anyone who did not read the paper: FIRE/J stands for Fast Implementation of Regular Expressions for Java, and from the outside it looks like java.util.regex, on purpose:
Pattern p = Pattern.compile("(\\d+)\\.(\\d+)");
Matcher m = p.matcher("3.14");
m.matches();            // true
m.group(1);             // "3"
m.group(2);             // "14"
p.matches("3,14");      // false
The difference is what compile does. The JDK parses the expression into a tree of node objects and, on every match, walks that tree with the input, backtracking when a branch fails. FIRE/J parses the expression into a deterministic finite automaton, a table of states and transitions in which every character leads to exactly one next state, and then writes a Java class for that automaton, loads it, and hands you an instance. Ask the engine for the source of the class and you get this, for [0-9]+\.[0-9]+, trimmed to two of its four states:
public final class GeneratedRegex extends CharArrayRegex {
    protected int walk(int offset) {
        final char[] arr = arrayBuffer;
        int state = 0, returnValue = -1;
        for (int i = offset; i < length; i++) {
            int c = arr[i];
            switch (state) {
                case 0:
                    if (c >= 48 && c <= 57) { state = 3; break; }
                    pos = i; return returnValue;
                case 3:
                    if (c == 46)             { state = 2; break; }
                    if (c >= 48 && c <= 57) { state = 3; break; }
                    pos = i; return returnValue;
                /* ... */
            }
        }
        pos = length; return returnValue;
    }
}
There is no regular expression left in there. No node objects, no backtracking, no table lookup; the automaton has become control flow, and the JVM's just-in-time compiler turns it into native code like any other Java method. That is the "Java source" flavour of the paper. The "bytecode" flavour goes one step further and does not even keep the loop and the switch: each state is a block of instructions and each transition is a goto straight into the next block, which the JVM's verifier permits and javac would never emit. The price of all this is obvious from the listing: compiling an expression means generating and loading a class, which is thousands of times slower than building a tree of nodes, so a cache in front of the compiler is part of the design. The bet of the paper was that, in a server that compiles a pattern once and matches it a million times, the compile cost vanishes and the generated code's speed remains.
Last week I dusted the engine off, brought it up to 2026, and then did the thing one should always do with an old paper and rarely does: I reran section 6 as written, on the machine I have now, against the engines that exist now. FIRE/J is still the fastest participant in every column. It also had to fight for it: the runtime it sits on has changed the terms of the contest, and the 2007 design, run unchanged, would have lost to a transition table. This post is about that second sentence.
What the paper measured
The protocol is simple and I have kept it. Every engine runs in its own process. An expression is compiled five times and the median is its compile time. Then a warm-up, then a long loop of matches against one sample input, and the amortised time per match is the match time. Two hand-crafted expressions give the clean picture: an IPv4 address matcher against a fifteen-character address, and an Apache access-log matcher against a 193-character log line. A corpus of real-world expressions collected from regexlib.com gives the messy one, narrowed to the rows every engine accepts, and plotted against Ehrenfeucht and Zeiger's size and length measures of the expression. Finally a break-even: how many matches before the slow compiler with the fast matcher has paid for itself against the fast compiler with the slow matcher.
In 2008 the numbers looked like this:
| Engine | IPv4 (µs) | Apache log (µs) | Compile (µs) |
|---|---|---|---|
| FIRE/J, bytecode | 0.1 | 1.2 | 115,690.0 |
| FIRE/J, Java source | 0.2 | 4.9 | 260,904.0 |
| dk.brics.automaton | 0.3 | 4.6 | 43,992.0 |
| Java 5 SDK | 3.5 | 33.8 | 62.0 |
| Perl 5.8 | 3.8 | 6.0 | 0.9 |
Read the story in the ratios. The generated bytecode is three to four times faster than the only other DFA on the JVM, dk.brics.automaton, which walks a transition table; it is 35 times faster than the JDK's backtracking engine; and it costs a tenth of a second to compile, which is absurd, so a cache sits in front of it and the break-even against Perl is around 24,000 matches. The paper's argument was that in a long-running server the compile cost disappears and the factor of three to thirty-five stays. That was true.
What changed
Three things, and I want to keep them apart, because they pull in different directions.
The engine. The 0.71 release spoke POSIX extended syntax. The 2026 engine reads the Perl dialect that people actually write, as far as a DFA can follow it: shorthands, escapes, anchors, non-capturing and named groups, and a preprocessor that refuses backreferences and lookaround at compile time rather than pretending. It recovers capturing groups after the DFA has said yes. And the code generator has two designs the paper did not have: the goto-threaded emitter is back (I had lost it to a switch loop in a rewrite along the way) and, on top of it, a class map: a static table that folds every character into its equivalence class, so a state with many ranges becomes one array lookup and one jump table instead of a compare-and-branch pair per range.
The benchmark. Ten engines instead of six, and three corpora instead of one: the paper's two expressions, the 2007 regexlib dump the paper drew on (917 rows), and 3,311 expressions from regex101.com. Beside the JDK and dk.brics.automaton there are now RE2/J, Joni (Oniguruma on the JVM), Perl 5.34 and CPython 3.14, the last two timing themselves inside their own process. Only rows every participant compiles are compared: 823 and 3,200 of them. The medians of three runs on an Apple M4 Max with JDK 26, now in nanoseconds per match:
| Engine | IPv4 (ns) | Apache log (ns) | regexlib 2007 (ns) | regex101 (ns) |
|---|---|---|---|---|
| FIRE/J, class map | 8.5 | 118 | 6.1 | 5.6 |
| FIRE/J, compare chains | 10.8 | 210 | 6.4 | 6.0 |
| FIRE/J, switch loop | 19.8 | 466 | 10.3 | 7.4 |
| FIRE/J, interpreter | 59.3 | 1,410 | 22.1 | 12.9 |
| dk.brics.automaton | 13.1 | 440 | 8.1 | 5.9 |
| java.util.regex | 196.0 | 1,080 | 64.1 | 40.2 |
| RE2/J | 506.0 | 4,210 | 207.0 | 264.0 |
| Joni | 393.0 | 1,090 | 168.0 | 121.0 |
| Perl 5.34 | 524.0 | 688 | 231.0 | 172.0 |
| Python 3.14 | 360.0 | 588 | 104.0 | 78.6 |
The runtime. This is the one the post is about. Everything is a thousand times faster than the 2008 table, which is what eighteen years of hardware do. But look at the JDK column: its engine went from 35 times slower than FIRE/J on IPv4 to 23 times, and from 28 times slower on the Apache line to 9. Nobody rewrote java.util.regex into a DFA. The backtracker got a better compiler underneath it. And the compile cost went from 116 milliseconds to 219 microseconds, five hundred times, without the code generator getting cleverer at all; defining a class became cheap. The break-even is now four to six thousand matches instead of twenty-four thousand.
The battle, eighteen years on
The paper was a battle between two ways of running a regular expression: interpreting it, whether by walking a tree of nodes or a transition table, and generating code for it. So read the 2026 table as a scoreboard of that battle, and read it critically, because the easy reading is wrong twice.
The first thing to see is that most of the field never caught up. Everything got a thousand times faster since the Pentium 4; the ratios did not move. java.util.regex is still 7 to 23 times slower than the generated code; RE2/J is 35 to 60 times slower; Joni, Perl and Python are 5 to 60 times behind, the low end on the long Apache line, where the input is what costs and every engine pays for it. These are 2026 engines on a 2026 core, and a backtracker still spends 40 to 260 nanoseconds on a real-world expression, because its inner loop is still an interpreter walking node objects. Technological progress lifted every boat by the same factor and left the distance between them exactly where the paper found it. The generative approach won in 2007 and it wins now, in every column, by the same order of magnitude.
The second thing to see is how the one engine that did come close managed it. dk.brics.automaton is the other DFA, a transition table and one loop, and on the corpora it is within a third of FIRE/J and, on regex101, within five percent. But look at the FIRE/J rows above it. The switch loop, which is the paper's "Java source" design, loses to the table on both corpora: 10.3 against 8.1, 7.4 against 5.9. The compare chains, the paper's "bytecode" design brought back as it was, are level. Only the class map, which did not exist in 2007, is ahead. The 2007 code generator, run unchanged on a 2026 JVM, would be beaten by a transition table. The gain from eighteen years of progress did not arrive by itself; it had to be collected, with very specific work: threading the states instead of looping over them, folding the character ranges into a static class table, copying a window of the input instead of the whole of it. Each of those is a small idea with a measured effect, and without all three the generated code is not the fastest engine on the list.
And the naive conclusion, that 5.6 against 5.9 nanoseconds is a difference nobody will notice, is the wrong one to draw. On a laptop it is nothing. In the place regular expressions are actually run at scale, a log pipeline or a firewall or a mail filter that matches billions of lines a day on hundreds of cores, five percent of the matching budget is five percent of the machines, and 25 percent, the regexlib figure, is a line in a capacity plan. The reason the paper measured amortised time over a million matches is that this is the regime the engine was built for; the per-match nanosecond is the unit that scale multiplies.
None of that changes the uncomfortable part, and it is the part that took me three rounds of work on the benchmark harness to see. The first standings had dk.brics.automaton two to five times ahead of FIRE/J on the corpora, and every one of those numbers was made by the JVM's execution environment, not by either engine. The original idea, a class per expression with the automaton compiled into it, was attacked by the runtime it was written for. The generated code did not get slower; the JVM changed the terms on which code is allowed to be fast, and a design from 2007 had to be defended on the new terms before it could win. That is the point of the rest of this post.
What the JIT does now that we did by hand
The paper's central trick is to remove the interpretive dispatch. A table-driven DFA does, per character, a load from the table and an indirect jump to whatever comes next; the generated code knows the next state statically, so the jump is direct and the table is gone. In 2007 that was worth a factor of three, and the reason was partly the runtime and partly the silicon underneath it. A Pentium 4 had a pipeline over twenty stages deep and a mediocre indirect-branch predictor; every state transition that the predictor got wrong cost as much as a dozen characters' worth of work. Making the branches direct meant the predictor did not have to guess.
A 2026 core guesses very well. Its indirect predictor keys on the history of recent branches, and a state machine's dispatch is exactly the kind of pattern that history predicts: after "digit, digit, dot" the next state is usually the same one it was last time. The table walk that used to stall now runs speculatively, in order, and the load from the transition table hits the first-level cache because the whole table fits there. The hardware is doing at run time, from observed behaviour, what the code generator did at compile time from the automaton. That is where the factor of three went.
The JIT then adds three costs the paper never had to pay, and they all come from the same design decision: a class per expression.
A compilation per expression. HotSpot compiles methods, not programs. The automaton library has one match loop, and after it has been compiled once it is hot for every expression ever loaded. FIRE/J's thousand expressions are a thousand methods, each of which starts in the bytecode interpreter, gets profiled, is compiled by the first tier, and then queues behind the other 999 for the optimising compiler. The corpus tables show it directly: the cold first call of a FIRE/J expression is 2.8 microseconds where dk.brics.automaton's is 0.17, seventeen times slower, because one is being interpreted and the other is native code that was warm before the pattern existed. My first harness warmed each pattern with a fixed twenty thousand calls, which was above every JIT threshold I knew of, and it was still measuring first-tier code on half the rows. The queue was the threshold. The harness now warms each pattern until its pace stops changing.
An inlining budget per method. The generated walker reads its input from a char[] copy, which the paper called the buffer subsystem and which I tried to remove: read the String in place through charAt and skip the copy. It made every corpus worse, by three times on the Apache line. A large generated method has one charAt call site per state, and past the inliner's size budget they stay calls. The tiny table loop has one call site and it always inlines. Big straight-line code is what the JIT is worst at; the small hot loop is what it was built for.
Profile-guided everything. Tiered compilation, escape analysis, loop unrolling, branch layout from observed frequencies: every one of these favours a loop that runs a billion times over a method that runs a thousand times and then is replaced by its neighbour. The automaton library gets all of them once. FIRE/J gets them per class, late, and pays for the profiling each time.
Put the three together and the run-time system has taken back a good part of what the code generator gave, and would have taken all of it from the 2007 design. The dispatch overhead we removed by hand is removed by the branch predictor; the specialisation we did at compile time, the JIT does from profiles; and the price of having a class per expression is one the paper's JVM barely charged and this one charges in full.
What is left for the code generator
Not nothing, and it is worth being exact about what. The gain that survives is not "no interpreter" but "the generator knows the automaton". The class map is the example: the generator can see that a state's forty ranges collapse into five character classes, precompute the map, and emit one lookup and one five-way jump. A table-driven engine could do the same and dk.brics.automaton in fact does something like it for its transitions, but it has to do it generically; the generator does it per expression, with the numbers in front of it. That is where the 3.7 times on the Apache line comes from, and the quarter over the compare chains on the corpora. It is partial evaluation, the old idea: whatever is known about the data before the run should be folded into the code before the run. The dispatch was never the interesting part of that. The knowledge was.
The other survivor is the worst case. Every backtracking engine in the table has a tail: Joni, Perl and Python each blew a sixty-second timeout on a handful of regex101 rows, and the JDK, which defuses the classic patterns, still spends sixteen milliseconds on its slowest. A DFA has no tail, generated or not, and that property is worth more to a server than the nanoseconds are.
If I were writing the paper today the claim would be smaller and, I think, more durable: compile the automaton to code because the interpreters are still an order of magnitude behind and will stay there; cache the class as if it were expensive, because the JIT will treat it that way; and expect the margin over a transition table to be a constant you have to earn against the runtime, not one the idea hands you. In 2007 we could write "a factor of three" and mean it. The factor is still there on the right expression. It is just that the JVM learned the trick.
And the engine itself is public now, two days after I wrote this: bkarak/firej-oss, under the Apache License 2.0, a Maven build on JDK 21 or later. It is the engine of Table 2, all four back-ends, with the JUnit suite and the two corpora it is tested against. The benchmark harness is not part of it. If you want to see the class in the listing above for yourself, the engine's toJavaSource prints it for any expression you give it (the switch form, which is the one you can read).
The numbers and the rest of the tables are on the FIRE/J page; the paper is here. And yes, the benchmark took three days to run and three rewrites to trust, which is roughly the ratio it had in 2007 as well. Some things the JIT cannot optimise :)