Dyck Word Generator
Lists the Dyck words of a given length in lexicographic order, ranks and unranks them, and spells each one as brackets, bits, a nested set of pairs or a non-crossing partition.
A Dyck word is a string of n opening and n closing brackets in which no prefix closes more than it has opened: (()()) is one, ())(() is not. There are Cn of them, the n-th Catalan number. This program lists them all in lexicographic order, with the algorithm Kostas Manes and I worked out in 2002, and it finds the place of any word in that list, or the word at any place, with Kostas's ranking of 2004. The source has been public since October 2026: one C99 program, with no dependencies.
Running it
git clone https://github.com/bkarak/dyck-words.git
cd dyck-words
make && make test
./dyck 3
Every word goes on a line of its own, in one of five spellings chosen with -f. For n = 3:
dyck 3        -f bits   -f pairs             -f ncp         -f positions
()()()        101010    {1,2} {3,4} {5,6}    {1} {2} {3}    1 3 5
()(())        101100    {1,2} {3,6} {4,5}    {1} {2,3}      1 3 4
(())()        110010    {1,4} {2,3} {5,6}    {1,2} {3}      1 2 5
(()())        110100    {1,6} {2,3} {4,5}    {1,2,3}        1 2 4
((()))        111000    {1,6} {2,5} {3,4}    {1,3} {2}      1 2 3
bits writes an opening bracket as 1 and a closing one as 0, which is what the 2002 and 2004 programs wrote. Read as binary numbers those are 42, 44, 50, 52 and 56, so the order is simply the order of the numbers. pairs is the nested set of pairs the word stands for: 2n points on a line joined two by two with arcs that never cross, each arc a matching pair of brackets. ncp is the non-crossing partition of 1..n it stands for (below), and positions is where its opening brackets are, which is all the program actually keeps.
$ dyck -c 18
477638700
$ dyck -r '(()())'
4
$ dyck -u 4 3
(()())
-c walks every word and prints only the count, checked against Cn. -r gives the rank of a word and -u the word at a rank; both read one per line from standard input when given -. Ranks need n ≤ 36, because C36 = 11,959,798,385,860,453,492 is the last Catalan number that fits in 64 bits. Listing has no limit but patience.
Shift and push
The program keeps a word as the positions of its opening brackets. Each one has a home, its place in the smallest word ()()…(), and it can sit anywhere after the bracket before it, up to its home. Moving a bracket left makes the word bigger, so the list runs from ()()…() to ((…)), and the next word always comes from one of two moves, which Kostas named:
- Shift. If the last opening bracket has room, it moves one place to the left.
- Push. If it has none, walk left along the run of adjacent opening brackets it ends until one has room, move that one a place to the left, and send every bracket after it back home. If none has room, that was the last word.
()()()   1 3 5   shift: 5 to 4
()(())   1 3 4   push:  4 is against 3, so 3 moves to 2 and the last goes home to 5
(())()   1 2 5   shift: 5 to 4
(()())   1 2 4   shift: 4 to 3
((()))   1 2 3   push:  nothing has room, so the list is done
The push can walk the whole word, but it is rare, and how rare is exact. A word needs one when its last two opening brackets are adjacent, and those words pair off one to one with the Dyck words of length 2(n−1), so the push runs Cn−1 − 1 times. Cn/Cn−1 = (4n−2)/(n+1) tends to 4, which means three words in four come from a shift, two letters changed. For n = 18 that is 347,993,910 shifts against 129,644,789 pushes, counted.
Ranking
The rank of a word is its place in the list, and Kostas's note of July 2004 computes it without walking the list. Number the opening brackets from the right, and say the i-th is moved k when it sits k places left of its home; let d(i, k) be the number of words before the first one in which the i-th bracket is moved k. Then d(i, 1) = Ci, d(i, k) = d(i+1, k−1) − d(i+1, k−2), and the rank of a word is 1 plus d(i, k) over all its brackets. Unranking runs the sum backwards. The note prints the table for n = 10 and the program's matches it entry for entry; the diagonal sums to 16,795, which is C10 − 1, the rank of the last word less the 1 it starts from. The d(i, k) are the entries of Catalan's triangle, as it happens.
Pairs and partitions
The non-crossing partitions of 1..n are counted by the Catalan numbers too, and Kostas's notes of March 2002 spend most of their pages on why. Shade the regions under the arcs alternately, starting under each outermost arc, and put a point in each gap between neighbouring points: the shaded gaps are always (1, 2), (3, 4), …, (2n−1, 2n), and two of those points go in the same block when they sit in the same shaded region. In the program that comes down to reading the word two letters at a time:
| Letters | Point k |
|---|---|
(( | opens a block |
)( | joins the innermost open block, which stays open |
)) | joins the innermost open block and closes it |
() | is a block on its own |
So (()()) is ((, )(, )), the partition {1,2,3}. The notes give all fourteen partitions for n = 4, and dyck -f ncp 4 prints the same fourteen in the same order.
How fast
Measured on an Apple M4 Max with the repository's make bench, best of three. Writing goes to /dev/null, so the figures are the program's and not a disk's.
| n | Words | Count | Write them all | Output |
|---|---|---|---|---|
| 16 | 35,357,670 | 0.05 s | 0.21 s | 1.2 GB |
| 17 | 129,644,790 | 0.17 s | 0.78 s | 4.5 GB |
| 18 | 477,638,700 | 0.61 s | 3.11 s | 17.7 GB |
| 19 | 1,767,263,190 | 2.28 s | 12.81 s | 68.9 GB |
| 20 | 6,564,120,420 | 8.45 s | 41.55 s | 269.1 GB |
Each n costs about four times the one before, the same (4n−2)/(n+1), so n = 24 would take half an hour to count and n = 30 two months; any single word up to n = 36 is one -u away. In 2004, Kostas's shift/push counted n = 18 in 10 s and n = 20 in 2 min 22 s on a 2.4 GHz Celeron. The same code, compiled today, takes 0.41 s and 5.6 s: twenty-two years of hardware bought about twenty-five times, on an algorithm that did not change. My nsp-classic of 2004, which this program replaces, writes the 17.7 GB of n = 18 in 14.1 s on the same machine, against 3.1 s here, because it spells every word out from scratch where this one changes two letters.
Source
The code is at bkarak/dyck-words (external link, opens in a new tab), MIT-licensed. make test checks every format against a separate reference, ranking and unranking against the list itself, and the bits output for n = 1 to 14 against checksums of what nsp-classic writes for the same n; the two agree byte for byte, through n = 15 and 300 MB when it was checked. The 2004 programs computed Cn in a double and counted up to it; compiled today, that value goes inexact at n = 14 and rounds up at n = 24, where nsp-classic would write one word too many. This one stops when there is no successor.
The Visual Basic and C++ programs Kostas wrote, my nine C variants and the notes, which are in Greek, are not in the repository; the trace, the ranking and the partition reading above come from them. How it was brought back is in the post Nested sets of pairs, twenty-four years later.
The 2008 page
Dyck word generator is a utility that lexicographically generates a sequence of Dyck words for a specific length n. The algorithm used was designed by Kostas Manes and me.
Catalan numbers and Dyck words
Source: Wikipedia — Catalan number (external link, opens in a new tab)
There are many counting problems in combinatorics whose solution is given by the Catalan numbers. The book Enumerative Combinatorics: Volume 2 by combinatorialist Richard P. Stanley contains a set of exercises which describe 66 different interpretations of the Catalan numbers. Following are some examples, with illustrations of the case C3 = 5.
- Cn is the number of Dyck words of length 2n. A Dyck word is a string consisting of n X's and n Y's such that no initial segment of the string has more Y's than X's. For example, the following are the Dyck words of length 6:
XXXYYY XYXXYY XYXYXY XXYYXY XXYXYY
- Re-interpreting the symbol X as an open parenthesis and Y as a close parenthesis, Cn counts the number of expressions containing n pairs of parentheses which are correctly matched:
((())) ()(()) ()()() (())() (()())
- Cn is the number of different ways n + 1 factors can be completely parenthesized (or the number of ways of associating n applications of a binary operator).
Usage
nsp <length>
For the output a binary format is used and the results are stored in the file output.result. The source code is not available. Be advised that this implementation uses double for the calculation of the Catalan number. Consequently, this will not work accurately when the length exceeds the data type's capacity.
Windows and Linux binaries were listed on the original page but were never uploaded; only the Mac OS X build is available. It is nsp-classic built for 32-bit Intel, and current macOS refuses it as a bad CPU type.
Illustration
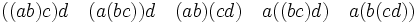
Downloads
- nsp-macosx.bz2Mac OS X, 32-bit Intel (2008)
These are the original files, kept as they were published. Most are decades old and are here as a record rather than as working software.